Research · Satire
Researcher Discovers LLM Confidently Wrong, Shocking Absolutely No One
A new study from Stanford finds that large language models frequently assert incorrect facts with high confidence, a phenomenon researchers have named 'hallucination' despite it already having that name for three years.
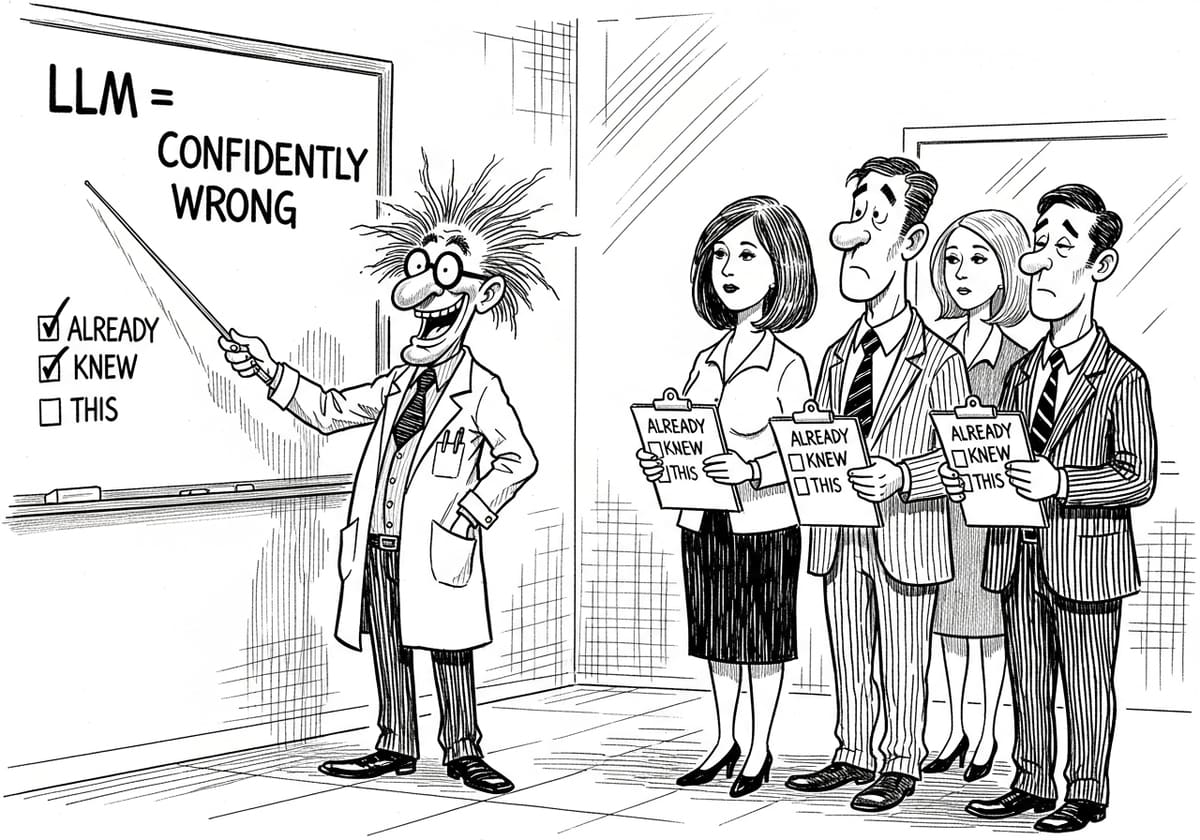
STANFORD — A team of researchers at Stanford University has published a paper documenting that large language models sometimes generate false information and present it as fact, a finding that arrives approximately three years after everyone who has used one of these systems learned this the hard way.
The paper, published in the fictional Journal of Machine Confidence, introduces a new evaluation benchmark called CONFABULATE that measures the rate at which models produce confident but incorrect statements.
“This is a significant finding,” said lead author Dr. Jessica Park, who acknowledged that the phenomenon has been discussed extensively in prior literature under the name “hallucination.”
The researchers prefer the term “confabulation,” which they introduced in their paper and which they define as “the generation of plausible-sounding but factually incorrect content,” which is also the definition of hallucination.
Among the study’s findings: models are more likely to confabulate about obscure topics than common ones, they become more confident when asked follow-up questions, and they can be prompted to confabulate less if you ask them nicely.
“We’re excited about the implications,” said Park.
At press time, three companies had announced they had solved confabulation.